Official source
1 How Google Search crawls pages
How does Google Search crawl pages? This walk-through goes from finding URLs to fetching and rendering them, and explains what Googlebot is and why sitemaps can help.
Older: check current guidanceTopic
19 videos.
A page cannot appear in search until a crawler has found it and fetched it. Crawling is that first step. Sitemaps, internal links and server logs all play a part, and a crawler that wastes time on the wrong URLs can leave good pages unvisited.
Beginners can start with Google's own introduction to how it crawls pages, recorded in 2024 and quick to watch. For a recent Google conversation about sitemaps, there is Do sitemaps still matter? with Martin Splitt and John Mueller. Readers ready for logs could try Crawling, indexing and logfiles from brightonSEO. Sources range from Google Search Central to tool vendors and a university lecture on how crawlers are built. Anything from 2020 or earlier is worth checking against today's guidance.
Practise with: Tools for crawling and site audits
Official source
How does Google Search crawl pages? This walk-through goes from finding URLs to fetching and rendering them, and explains what Googlebot is and why sitemaps can help.
Older: check current guidanceSells in this field
Search engine indexing is broken into crawling, indexing and ranking, followed by ways to control what gets indexed so that content is found.
Sells in this field
Technical SEO problems are the focus as experts from Wix and Deepcrawl go through the fundamentals of keeping a site healthy for search engines.
Older: check current guidanceSells in this field
Getting pages crawled and indexed faster is the aim of this Wix webinar, where Fabrice Canel from Bing presents IndexNow and Crystal Carter answers common indexing questions.
Older: check current guidanceIndependent practitioner
Crawl budget is how many pages crawlers can get through in a set time, according to this BrightonSEO 2021 interview with Joanna Beech, which also covers how to deal with it.
Older: check current guidanceTrade press or conference
How Google crawls and indexes pages is the topic as Barry Schwartz of Search Engine Land puts live questions to Martin Splitt of Google about the technical side of search.
Older: check current guidanceOfficial source
Does crawling more often mean a better site? John Mueller, Lizzi Sassman and Gary Illyes untangle ideas about crawl frequency and site quality, and ask how crawling could be more efficient.
Official source
Do XML sitemaps still matter? Martin Splitt and John Mueller look back at their history, ask whether crawlers can work out site structure alone, and discuss why fetch warnings in Search Console worry owners.
Sells in this field
Sitemaps deserve more attention than they get, argues Carlos Manuel Sánchez Donate, who says they tell search engines and LLMs which parts of a site matter and suggests splitting them by content type.
Official source
Crystal Carter talks with Martin Splitt about a site that no crawling tool could crawl fully, the steps and tools used to fix it, and how monitoring can head it off.
Older: check current guidanceSells in this field
Log file analysis gets a short lesson in Semrush Academy's course, part four of seven, using the Log File Analyzer and its Googlebot activity graph to see how Googlebot crawls a site.
Older: check current guidanceTrade press or conference
Andor Palau goes through crawling, indexing and log files using real log file analysis data, with ideas for improving each area on your own site.
Trade press or conference
Does optimising crawl budget improve web traffic? Vanessa Fox joins this podcast episode to talk about how search engines discover, crawl and index content.
Teaching or conference talk
Web crawlers are responsible for a large share of internet traffic, according to this lecture, which explains how they work, why crawling is hard and gives a short look at Nutch.
Older: check current guidanceTeaching or conference talk
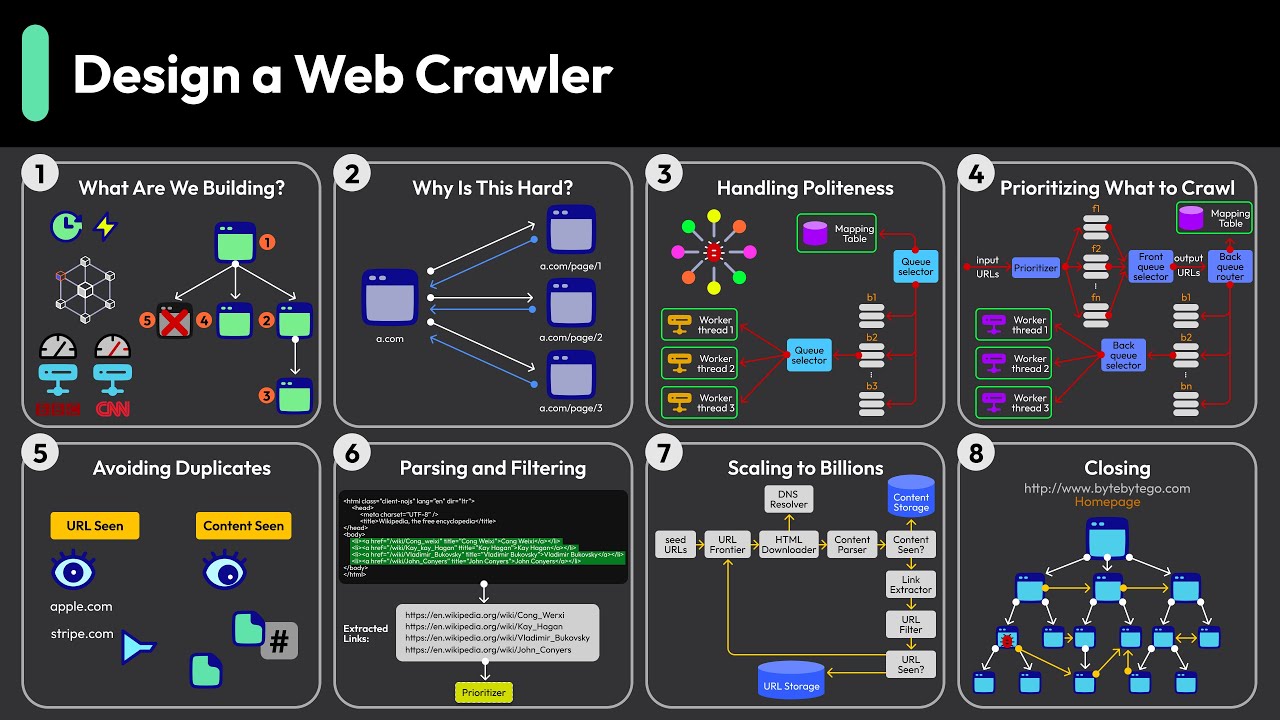
How would you design a web crawler for a system design interview? This walkthrough takes engineers through one possible answer.
Sells in this field
Log file analysis for SEO gets a panel discussion, with three technical SEOs talking through what to look for in server logs, hosted by Jason Barnard.
Older: check current guidanceSells in this field
Internal linking on big websites is harder when thousands of pages are thin or duplicated, the speaker says, and links are what turn a bunch of pages into a connected site.
Sells in this field
News SEO exposes a lot about how Google crawls, indexes and judges authority, argues Barry Adams, because Google must find and rank new articles quickly.
Older: check current guidanceSells in this field
Dawn Anderson explains what the AI era changes for crawling, indexing and technical SEO, and argues RAG works from a web index rather than live data.